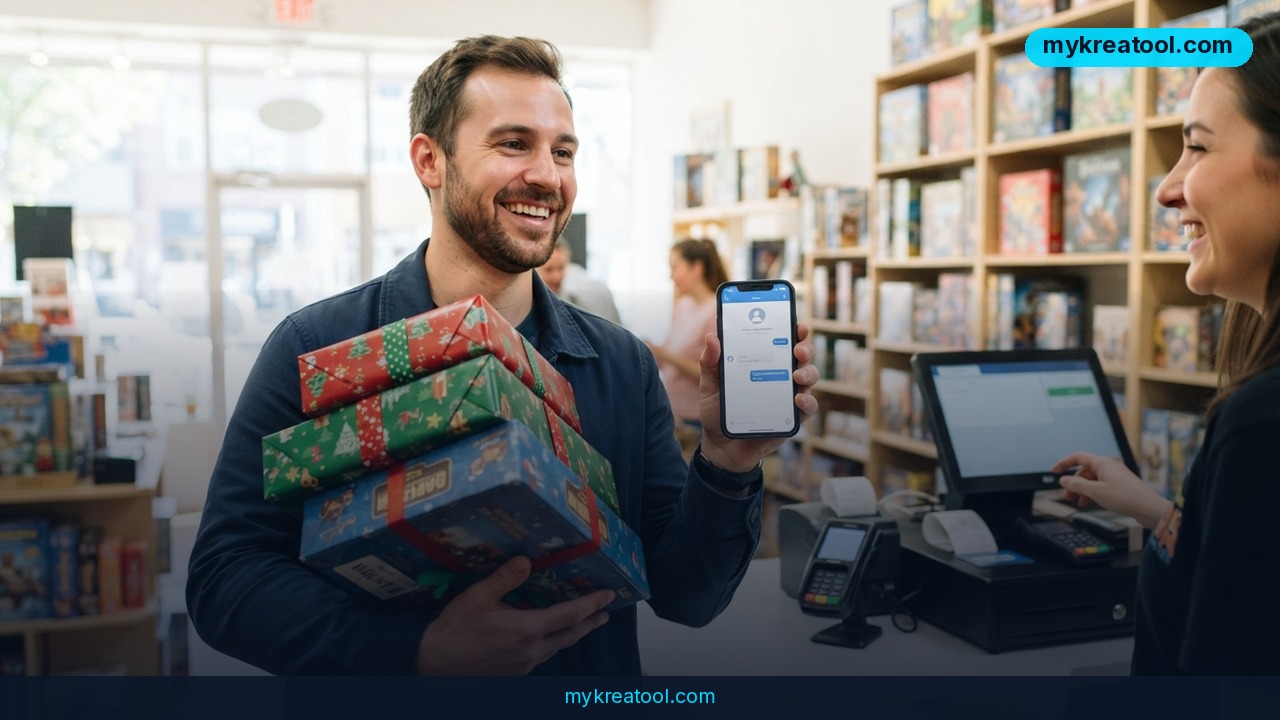
A shopper asked a store's chat window for a birthday gift — brother, turning 30, loves board games, $70 max — and the AI shopping assistant closed the sale on its own. No human stepped in. It asked one follow-up question, pulled three games off the shelf, applied a 20% discount and landed at $67.19.
That's the demo behind cart-agent, a freshly published open-source project that puts a 9-billion-parameter model on a laptop instead of a data center. Here's what actually happened, and why the boring parts are the interesting ones.
What happened
A $70 budget, three gifts, and a 20% discount
A shopper types into the store chat: 'gift for my brother, he's 30, he likes board games, up to $70.' The assistant doesn't guess. It asks one question back — when's the birthday? — and gets 'Friday.' That single answer changes everything, because Friday is five working days out, and this store's own policy gives a 20% discount on orders landing in that window. That's a rule the shop wrote, not something the model dreamed up.
So three gifts tagged at $83.99 total squeezed under the $70 ceiling and came out at $67.19. Here's the part worth remembering: the AI does the talking, but ordinary code — not the AI — adds up the total, applies the discount and fills the cart.
Only three of the eight steps use the AI
Every message runs through eight steps, and only three of them touch the model. The rest is plain software:
1. Read the message — AI, returns structured data, ~3.3 seconds
2. Ask follow-up questions — code, pulled from a config file
3. Shortlist products — backend database filter, ~22 ms
4. Choose products — AI, allowed to pick IDs from that shortlist only, ~4.3 seconds
5. Build the basket — code, fits items to the budget
6. Pull prices and total — backend, straight from the database, ~9 ms
7. Write the reply — AI, ~2 seconds
8. Verify the answer — code, checks the sums and the wording
Those numbers are medians across six logged conversations. Ask a question and you wait 3–7 seconds. Get product suggestions and you wait 9–15. All that code adds up to roughly 30 milliseconds — nearly all of the remaining wait is the model thinking.
The shop is fake, but the plumbing is real
Everything ships in one repository, nmrcs/cart-agent, wired together as a Node monorepo — that just means several apps in a single download, sharing one install. There's a mock storefront so you can run the whole thing on your own machine. Its catalog holds 64 products, each tagged with an age range, stock level and delivery time. Three are out of stock, and eight need batteries or film bought separately — exactly the kind of messy reality that breaks a naive chatbot. The author ran it past six fake shoppers, and it never once blew the budget or quoted the wrong total.
Under the hood it's a familiar stack: NestJS 11 and PostgreSQL on the back end, React 19 and Vite up front, and shared validation schemas so both sides agree on the same shapes.
The assistant also only talks to the shop through two requests. One searches products by age, price and delivery time; the other calculates the order total. Swap in your own two endpoints and it'll chat with a real store or marketplace instead of the mock one.
What it means for you
At home: the gift you'd otherwise spend an hour on
You've done this dance. You want a present for a nephew you see twice a year, you don't know his hobbies, and suddenly you have 14 browser tabs open. This pattern flips the conversation: the software asks for the four things it can't guess — age, budget, deadline, interests — and only then starts recommending. If you've already said 'he's 30, up to $70,' it skips those questions completely. No age and no budget means no suggestions at all.
At work: support that knows when to ask instead of guess
Anyone running a support inbox knows the pain of a bot that answers confidently and wrongly. The trick here is that the AI is never allowed to invent a price or a product ID. It picks from a shortlist the database handed it, then a separate chunk of code double-checks the final message. If you run a help desk, that's the architecture to steal: let the model phrase things, never let it do arithmetic.
In business: discounts that actually get applied
Most chatbots will happily tell a customer 'yes, you qualify for 20% off' and then leave your checkout to sort it out. Here the discount rule lives in code, the total is recalculated from the database, and the last step verifies the numbers in the reply. For a small shop, that's the difference between a chatbot that looks clever and one that quietly loses you money. And if you need help with the marketing side rather than the plumbing — product copy, ad angles, keyword ideas — the free AI tools at MyKreaTool cover that ground without a subscription.
For study and side projects: a template for honest agents
If you're learning how to build an AI agent, this beats most tutorials because it's deliberately boring in the right places. The model handles language, the code handles facts. Walking through those eight steps is a two-hour education in where AI actually belongs in a product pipeline — and where it's a liability.
For income: a service small shops will pay for
The setup is small enough to sell. A local shop with a modest catalog doesn't need a custom platform; it needs two API endpoints — two doors into its data — plus a config file. Two-day builds like that are a realistic freelance line, and the client's ongoing cost is a hosting bill, not a monthly token invoice.
How to try it right now
Step one is free, and you don't need a cloud account.
1. Install LM Studio. It's a free desktop app that runs AI models on your own computer. Search for Qwen3.5 9B and download the 4-bit version — it's about 6 GB, and the author ran it on a MacBook M3 Max.
2. Grab the code. The project is nmrcs/cart-agent, an open-source repository you can pull from GitHub. One install command covers all the apps included in it.
3. Point it at your model. Open the `.env` file — a plain text file of settings — and fill in three things: the address of your local server, the model name, and a key, which local servers usually accept even if you type nonsense. That file is the only place the model is configured.
4. Run the backend and the frontend. The backend handles catalog, cart and prices. The frontend gives you a storefront with the chat panel on the right. The assistant itself is a separate app with no database of its own.
5. Click through the demo. Ask for a gift under a specific price for a specific age, and watch the step tracker — 'Reading your message,' 'Choosing,' 'Writing a reply' — with a timer beside it. That tracker exists because streaming text is pointless when the reply takes 2 seconds out of a 15-second wait.
6. Edit the questions. The four questions live in a config file, not in the code. Reword them, translate them, or drop a slot entirely. That's the whole customization for a different kind of shop.
7. No Mac? No problem. Any OpenAI-compatible API works — OpenAI, OpenRouter, whatever you already pay for. You just change the address, model name and key in that same `.env` file.
Upsides and what changes
The big shift is cost and control. A 6 GB model on your own laptop costs nothing per message, keeps customer data off someone else's servers, and can't be switched off by a vendor's pricing change. The second shift is trust: because the AI only writes prose and the code owns every number, you get a chatbot that sounds human and still can't hallucinate a price. And the benchmark folder with real run logs means you don't have to take anyone's word for the speed — you can read the medians yourself.
Limitations
Be honest about the rough edges. It's a demo, not a product: the store is mocked, so you'll be writing those two API endpoints yourself against whatever platform you actually run. Everything runs locally and needs a machine that can hold a 6 GB model — fine on a modern laptop, painful on an old one. The responses aren't instant either; 9–15 seconds for a product recommendation will feel slow to shoppers raised on instant search, which is exactly why the interface shows a progress step instead of a typing animation. The AI also can't recommend anything outside the shortlist, so if your catalog is tagged badly on age or delivery time, the assistant will look dumb for reasons that have nothing to do with the model. And the questions config ships with four fixed slots — adapt it to your category, or you'll be asking board-game questions of a shoe store.
Conclusion
The interesting thing here isn't that a small model can chat about birthday gifts. It's where the author drew the line: AI for language, code for math, database for facts, and a verification step before anything reaches the customer. That pattern works whether you're selling board games or booking haircuts, and you can copy it this afternoon.
One action for today: install LM Studio, download Qwen3.5 9B in its 4-bit version, and ask it a shopping question yourself. Ten minutes in, you'll know whether a local assistant belongs in your stack — and you'll have a feel for the 3–7 second pause that decides how you design everything around it.
Comments 0