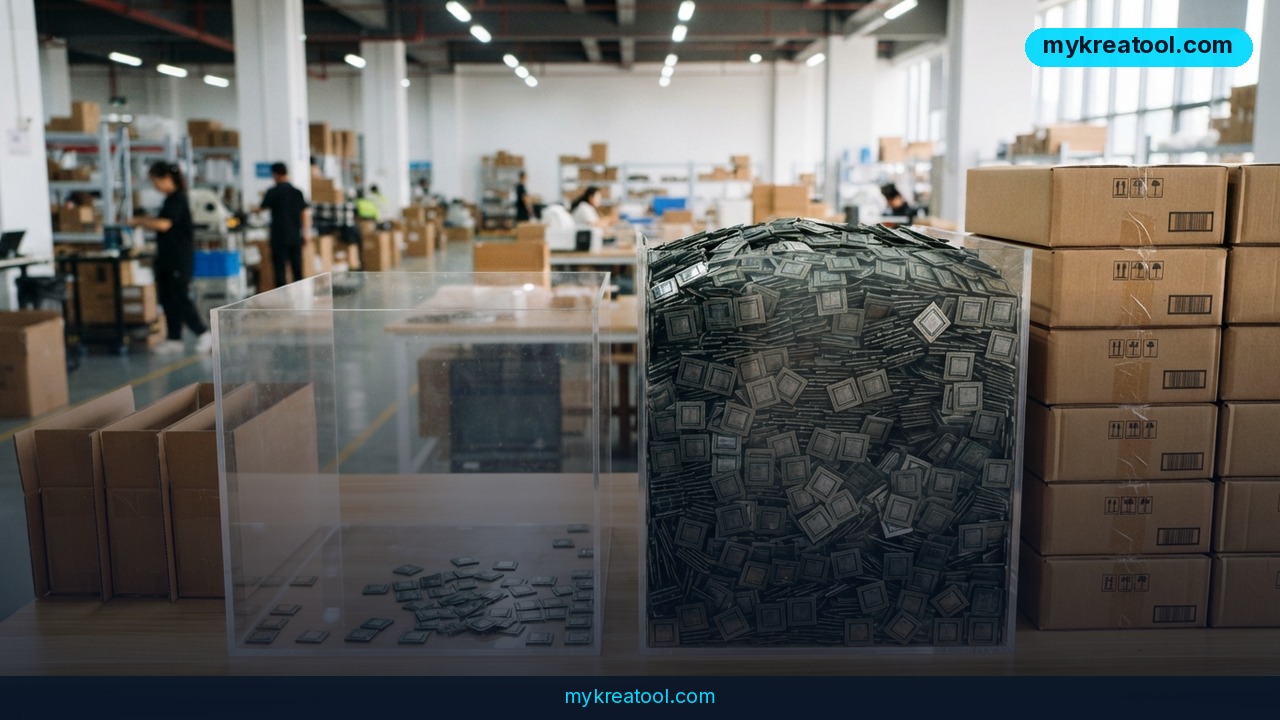
GLM-5.3-Flash is Z.ai's open-weight AI model with 320 billion parameters and 18 billion active per token through a mixture-of-experts design. It scores near GPT-5.6 Terra on benchmarks, costs $0.09 per task on the Intelligence Index — 7.5× less than the full GLM-5.3 — and runs entirely on Chinese AI chips, with no Nvidia hardware required.
What Is GLM-5.3-Flash? Key Specs at a Glance
Z.ai released GLM-5.3-Flash as an open-weight AI model that matches the performance of far more expensive systems while cutting inference costs by roughly 7.5 times. The model has 320 billion total parameters, but only 18 billion are active at any given time thanks to its mixture-of-experts (MoE) design — each request activates a small subset of specialized sub-networks instead of the full model, which is what keeps inference cheap despite the large parameter count. It ships under an MIT license, supports a 1-million-token context window, and its weights are freely downloadable on Hugging Face.
GLM-5.3-Flash Pricing: $0.15 per Million Tokens vs. Rivals
On Artificial Analysis's Intelligence Index, a benchmark task costs about $0.09 with GLM-5.3-Flash versus $0.68 with GLM-5.3 — a 7.5x reduction. Through Z.ai's API, that translates to $0.15 per million input tokens and $0.50 per million output tokens, roughly one-tenth the full-size model's rate.
See how the pricing holds up on reasoning-heavy tasks
Artificial Analysis found that about 90 percent of GLM-5.3-Flash's output tokens go toward internal reasoning rather than the final answer, so it burns more tokens to reach an answer even though the dollar cost per task stays low. Teams should benchmark real workloads rather than relying on index-level pricing alone before locking in cost projections.
Benchmark Scores: Where GLM-5.3-Flash Stands Against GPT-5 and Claude Opus 5
On Artificial Analysis's Intelligence Index, GLM-5.3-Flash scores 57 points at maximum reasoning effort — three points behind its larger sibling GLM-5.3 (60 points), and roughly on par with GPT-5.6 Terra and Muse Spark 1.2. On agentic benchmarks like GDPval-AA v2, GLM-5.3-Flash posts an Elo score near 1770, tying GLM-5.3 and Grok 4.6, and trailing only Claude Opus 5.
How Z.ai Broke Nvidia's CUDA Moat with Chinese AI Chips
GLM-5.3-Flash was trained and served entirely on Chinese AI chips, not Nvidia GPUs. Before its public launch, Z.ai quietly tested the model under the codename "ox-alpha" on OpenCode and OpenRouter, where it became the most-used model of the week without anyone knowing its origin. According to SemiAnalysis, that traffic peaked at 100 trillion tokens served per day, a scale previously assumed to require frontier-lab-grade Nvidia infrastructure.
How Z.ai rebuilt its inference stack without CUDA
CUDA, Nvidia's software layer connecting AI frameworks to its hardware, has been the industry default for nearly two decades — nearly every AI framework is optimized around it, and moving away means rebuilding compute kernels, memory access patterns, and performance tuning from scratch. Z.ai did exactly that, building its own serving stack on top of SGLang and splitting inference into independently scalable stages. The team reports this tripled throughput compared to its first attempt on the same chips, with an internal GLM-5.3-based agent helping optimize the pipeline. Z.ai says its hardware efficiency and per-token cost are now on par with common Nvidia GPUs, even without CUDA. Combined with recent results from OpenAI's own custom chip, this is being read as another crack in what analysts call Nvidia's CUDA moat.
How to Use GLM-5.3-Flash via API and OpenRouter Today
GLM-5.3-Flash is already accessible through Z.ai's API and via OpenRouter, so developers can plug it into existing pipelines with minimal changes — most tooling built for OpenAI-style chat completions works with only a base URL and API key swap. Because the weights are open under an MIT license, teams can also self-host it on their own GPU or accelerator clusters if they have the infrastructure, avoiding per-token API fees altogether.
For smaller teams and solo builders who don't want to manage API keys or self-hosting, pairing a low-cost model like this with ready-made interfaces is often the faster path. If you want to experiment with AI-assisted workflows without committing to paid infrastructure, MyKreaTool's AI chat lets you test prompts, generate content, and prototype ideas for free before deciding whether a heavier model or custom deployment is worth the investment.
Given the 1-million-token context window, GLM-5.3-Flash is also well suited for tasks that need to digest large documents, codebases, or long conversation histories in a single pass — think contract review, large-scale code refactoring, or summarizing lengthy research reports with document processing and summarization tools, all at a fraction of what comparable context windows cost elsewhere.
Who Benefits Most: Startups, Enterprises, and Solo Developers
Startups and indie developers stand to gain the most immediately. A 7.5x cost reduction on agentic and reasoning-heavy tasks means AI features that were previously too expensive to ship at scale — customer support agents, document processors, coding assistants — become financially viable for smaller budgets.
Enterprises running high-volume agentic workloads, like automated data extraction or large-scale content generation, benefit from the combination of near-frontier intelligence and dramatically lower per-task cost. Marketers and creators experimenting with AI content and text generation tools also benefit indirectly: as more Chinese labs like Z.ai push down pricing, competitive pressure tends to push Western providers toward similar cuts.
Hardware buyers and infrastructure planners benefit from a new data point: viable alternatives to Nvidia GPUs now exist for serving frontier-adjacent models at scale, which could eventually diversify procurement options and reduce dependency on a single supplier.
Risks to Watch: Token Inefficiency and Supply-Chain Exposure
With roughly 90 percent of output tokens spent on reasoning, actual usage bills can climb faster than the sticker price suggests for verbose or multi-step tasks — benchmark real workloads rather than relying on index-level pricing alone.
Supply-chain and compliance risks to check before deploying
There's also a geopolitical and supply-chain dimension. Running on Chinese AI chips means dependency on a different, less mature software and hardware ecosystem than the Nvidia/CUDA stack that most tooling assumes — migration tools, community support, and long-term chip availability are all less proven. As with any rapidly released open-weight model, enterprises should independently verify safety, data handling, and licensing terms before deploying GLM-5.3-Flash in production, especially for regulated industries or workflows touching sensitive data.
Conclusion
GLM-5.3-Flash shows that near-frontier AI performance no longer requires frontier-level spending or Nvidia hardware. At $0.09 per task and near-parity with GLM-5.3 on agentic benchmarks, it puts real pressure on both pricing and the assumption that CUDA is unavoidable. Track the latest AI model news and updates to see how competitors respond, before the next wave of cheaper, chip-diverse models makes today's pricing look expensive.
Comments 0