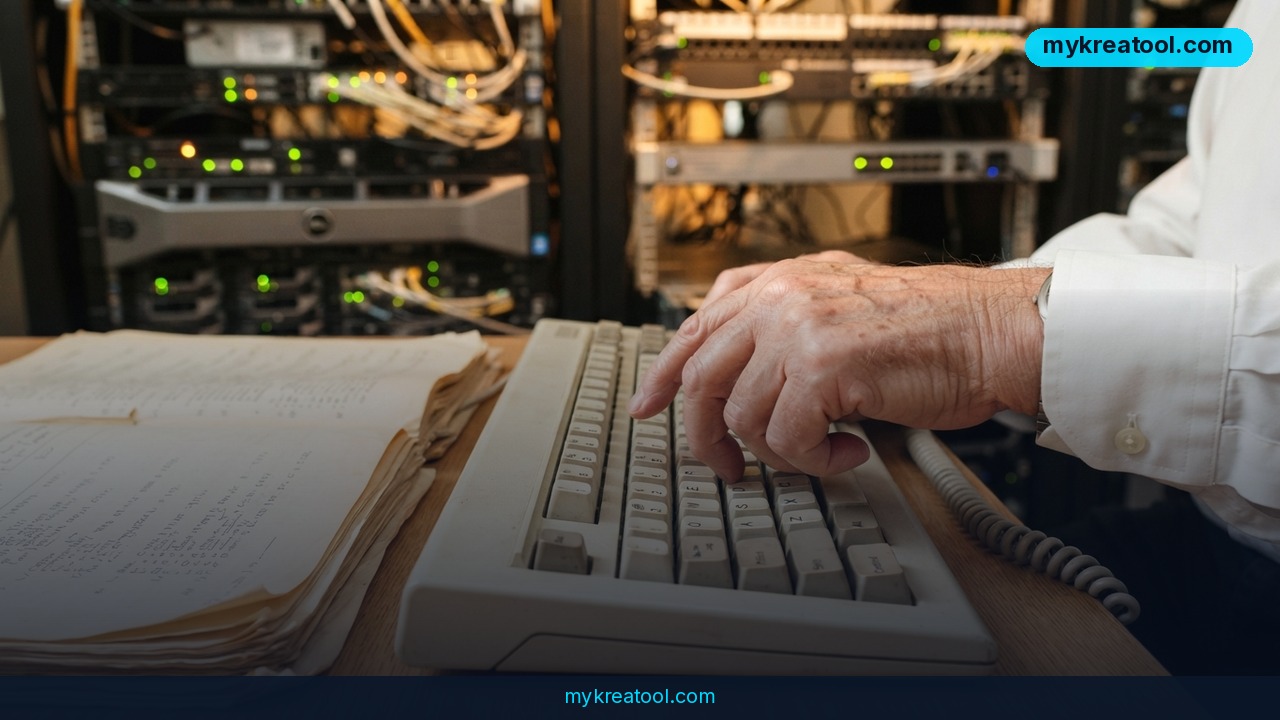
AI code generation has spent years getting very good at the popular languages — Python, JavaScript, the kind of code that fills up GitHub. Now it's turning to the older stuff that quietly runs your bank account.
On October 19, 2026, OpenAI published research on how its newest models handle what it calls low-resource programming languages: COBOL, Fortran, Visual Basic and OCaml. These are languages with far less public code for a model to learn from, yet a startling amount of the world's critical infrastructure depends on them. And the jump in this round of results isn't incremental.
What happened
OpenAI ran its latest models through two new evaluations and published the results alongside API costs, which is rarer than it should be. The short version: the models got dramatically better at writing and migrating old code, and they got cheaper at the same time.
Low-resource doesn't mean the language is rare in the real world. It means there isn't much of it sitting on the public internet for a model to study. Think of it as learning Spanish from thousands of films versus learning a regional dialect from two scratchy radio broadcasts. Millions of people might speak that dialect — the model just hasn't heard enough of it.
Why this old code is so hard to work with
COBOL supports more than 40% of online banking systems, 80% of in-person credit card transactions and 95% of ATM transactions, according to the figures OpenAI cites. Fortran turns up in weather forecasting and nuclear reactor safety analysis. Nobody is rewriting those systems over a weekend.
The maintenance problem is human, not technical. Documentation is often incomplete. The people who wrote the code have retired. Important business rules — how interest gets calculated, when a fee kicks in — may live nowhere except inside the program itself. So when a team moves to a modern language, the requirement isn't 'make it compile.' It's 'make it behave exactly the same.'
The two tests, in plain English
MultiLangBench asks a model to build a working SQLite-compatible database engine from scratch in one of 20 programming languages. (SQLite is the tiny database hiding inside your phone, your browser and half the apps you open.) Testers then compare the resulting database files against the real SQLite implementation, so the same checks apply no matter which language was used.
The second is a COBOL migration test: take an existing program, move it into another language, and see whether the behavior survives. Building something new and preserving something old are different skills, and OpenAI measured them separately.
The numbers
On MultiLangBench, GPT-6 Astra reached an average test pass rate of 87.4% across the 20 languages, up from 26.8% for GPT-5.6 Sol. Every language improved. COBOL went from 10.9% to 72.1%, OCaml from 25.6% to 85.8%, Fortran from 21.4% to 83.5%, and Visual Basic from 27.5% to 89.4%. Astra scored above 83% in 19 of the 20 languages.
A smaller model, GPT-6 Luna, hit 40.3% at roughly 78% lower estimated API cost. On the COBOL migration test, GPT-6.1 Sol scored 86.6% accuracy at low reasoning effort — against 5.4% for GPT-5.6 Sol — while costing 39% less. Crank the reasoning effort up and accuracy reaches 97.9%, which practically saturates the test.
What it means for you
At home: fewer 'our app is down' Saturdays
Every time a banking app freezes or an ATM declines a card that should work fine, an old COBOL program is usually somewhere in the story. Models that read and change that code more reliably mean fewer of those moments — and faster fixes when they do happen. You won't see GPT-6 Astra on your bank statement, but you'll feel it in how quickly the app comes back online.
At work: the migration project that keeps slipping
Almost every large company has a creaking legacy system that nobody wants to touch. The person who understood it left, the documentation is a mess, and every quarter the migration slides into the next one. A model that scores 86.6% on behavior-preserving COBOL migration doesn't finish that project for you — but it gives your team a real first draft and a way to see inside the black box.
For your business: legacy fixes stop being a luxury
If you run something small — a booking system, an invoicing tool, a script only one contractor understands — you've probably been quoted serious money just to have someone look at it. Cheaper, more capable models put a plain-English description of what that software does within reach. That alone changes the negotiation, because you're no longer held hostage by the one person who knows the code.
For students and self-taught coders
Old languages used to be a wall: too few tutorials, strange syntax, nothing to practice on. That's shifting. If you want to see how a model handles code you don't recognize, paste a short snippet into free AI tools like the ones at MyKreaTool and ask for a line-by-line breakdown — a cheap way to find out whether a language is worth your weeks before you commit.
For creators: the small tool you keep sketching
The MultiLangBench result isn't only about old systems. Building a working program from scratch got better in all 20 languages tested, at a lower cost. That's the difference between having an idea for a small calculator, tracker or converter and actually shipping a rough version of it this month. The gap between 'I had an idea' and 'here's a prototype' keeps getting smaller.
For income: where the scarce skill moves
COBOL contractors have been scarce for decades, and scarcity is exactly why the pay is good. If translation becomes mechanical, the premium shifts to verification — knowing which rules must never change, writing the tests, signing off on behavior. That's a skill you can build on purpose, and it's far less crowded than 'I know Python.'
How to try it right now
1. Start free with one tiny piece of code. Pick a single calculation — a fee, a tax rule, a date adjustment — not a whole system. Paste it into a free AI chat tool and ask: 'Explain what this does line by line, then rewrite it in Python.' The explanation is worth more than the rewrite.
2. Move up to ChatGPT for anything real. The models in the research post (GPT-6 Astra, GPT-6 Luna, GPT-6.1 Sol) are OpenAI models, so ChatGPT is where you'd look for them. The post doesn't spell out which plan gets which model, so check what you actually have access to before you plan a project around it.
3. Ask for tests, not just code. Say: 'Give me five example inputs and the exact output the original produces for each.' That's the behavior-preservation habit the COBOL migration test is actually measuring.
4. Run old and new side by side. Same inputs, same expected outputs, compare results. If they differ, you've found either a bug or a business rule nobody documented.
5. Keep a human in the loop for anything touching money. Ask a colleague who knows the business rules to review the output before it goes anywhere near production.
6. Go one routine at a time. Migrate a slice, test it, ship it, repeat. Big-bang rewrites are how these projects die.
Upsides and what changes
The gains are real and they're broad. Accuracy on COBOL migration jumped from 5.4% to 86.6% at low reasoning effort, and up to 97.9% with more effort. Costs fell in both tests — 39% less on the migration work, and roughly 78% lower estimated API cost for the smaller model. Every one of the 20 languages improved, so this isn't a single lucky result.
Maybe the most interesting change is institutional. Business rules that exist only inside old code can finally be read, explained and written down. That turns a black box into something a new hire can understand — and it makes smaller teams able to attempt migrations they'd have written off two years ago.
Limitations
Be clear-eyed about what a benchmark is: a lab test, not your mainframe. A 97.9% score means the evaluation is nearly maxed out, not that the problem is solved — and the missing slice is exactly where a bank's overnight batch job lives. The model also can't know rules that were never written down, so it will confidently produce plausible code that quietly changes behavior. You still need someone who understands the business, a test harness that proves behavior is preserved, and a review process. And nobody outside OpenAI has published results running these models against your particular pile of 30-year-old code, so treat the numbers as a strong signal, not a warranty.
Conclusion: Your One Action for Today
Pick one small, dull piece of code you've been avoiding — a spreadsheet macro, a legacy report, a snippet a former colleague left behind — and ask ChatGPT to explain it line by line. Fifteen minutes, zero risk, and you'll find out whether the new generation of models is as useful on your real work as it looks in a research post.
Comments 0